Best Industrial Shredder for Heavy-Duty Use: How to Choose the Right Model
2026-09-15
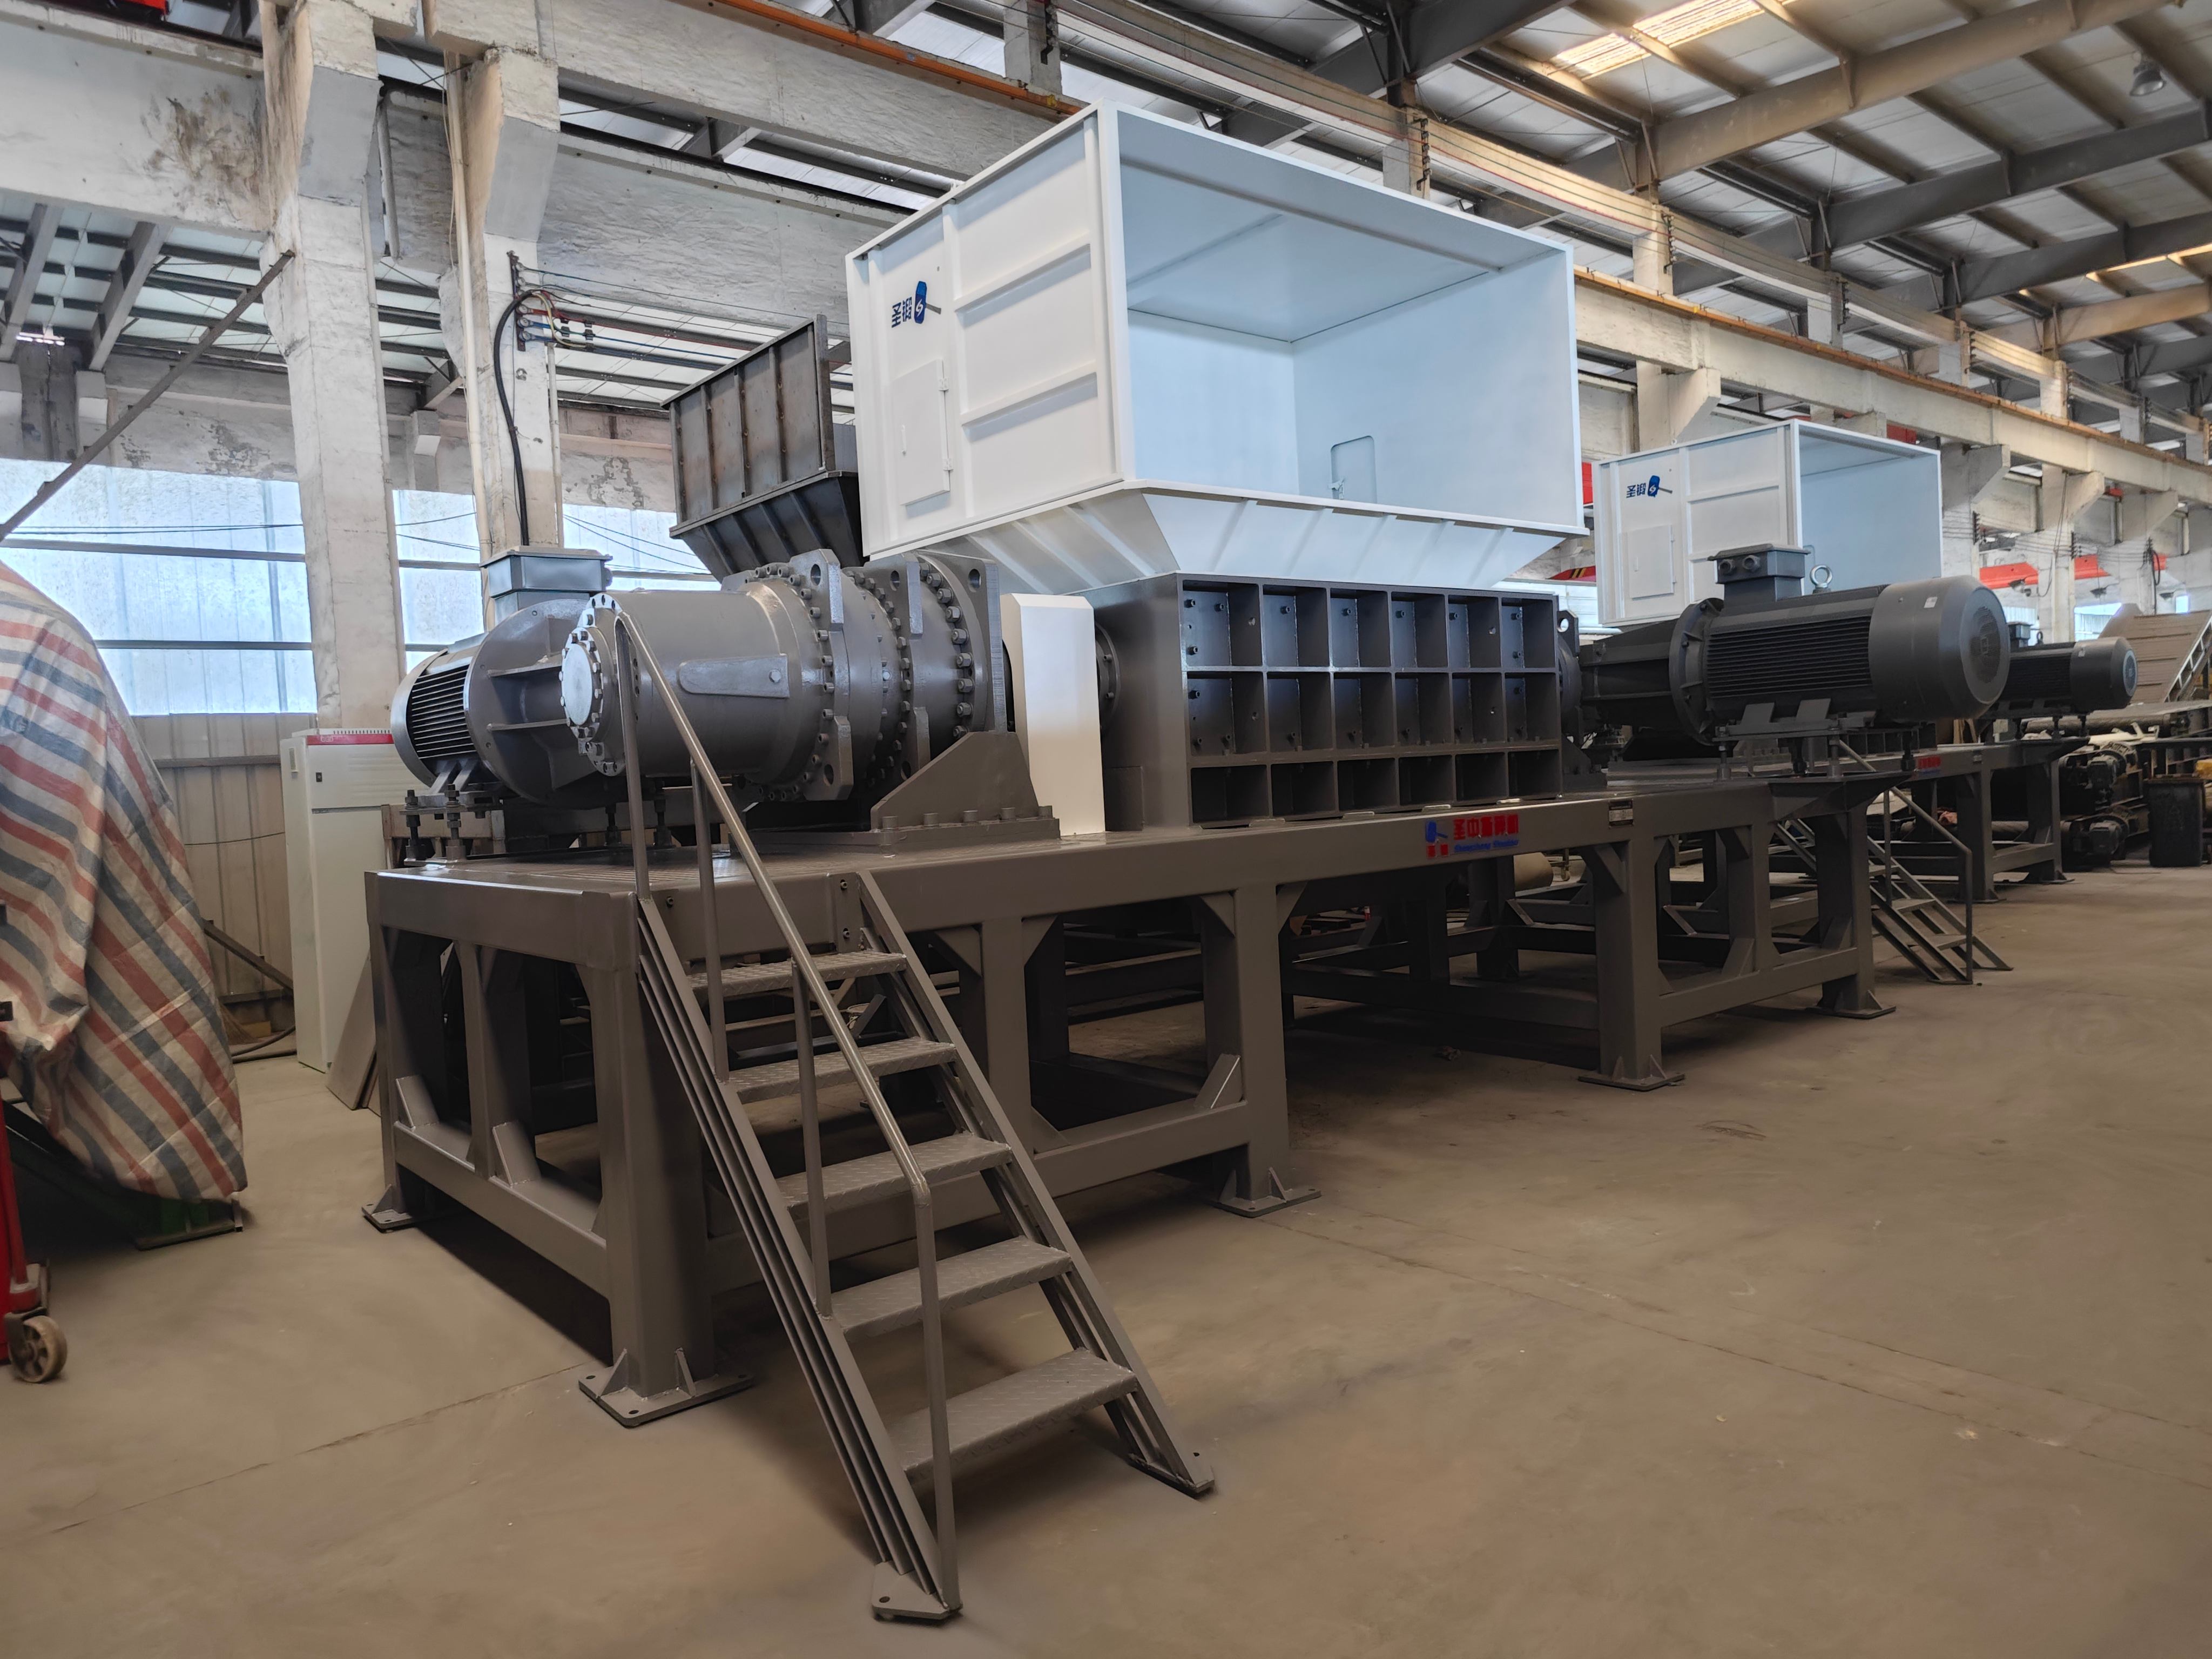
Choosing a heavy-duty industrial shredder isn’t just about horsepower — it’s about matching the machine to the materials you actually feed it. Scrap yards, recycling plants, and manufacturing floors all have different failure points, from jammed rotors to worn-out cutting blades. A model that works flawlessly on aluminum may struggle with thick steel or bulky e-waste. In this guide, we break down what separates a reliable workhorse from a costly mistake, and why Shengzhong Shredder builds machines that hold up when the feed gets ugly.
What Your Shredder Will Actually Eat Determines the Right Build
People get hung up on horsepower and sheet capacity, but the real question is what you'll actually feed the machine day after day. A pile of dry branches from a backyard cleanup behaves nothing like a steady stream of wet leaves or a stack of old cardboard boxes. Build choices that look identical on a spec sheet can feel completely different once you start pushing material through.
If your shredder mostly sees soft, green garden waste, you'll want a build focused on shredding blades and a wider hopper that lets you dump armfuls of material without constant jamming. For woody prunings or dried brush, a heavier flywheel and stronger cutting mechanism matter more than raw speed. Matching the internals to your typical load saves you from standing there poking at a clogged chute while the motor whines.
Think about how often you'll run it too. A weekend gardener with a small fruit tree and some hedge clippings can get away with a lighter, simpler build that's easy to move and store. Someone processing storm debris or maintaining a larger property needs a design that can chew through tougher chunks without overheating. The right build isn't the one with the biggest numbers — it's the one that handles your actual pile without complaint.
Peak Throughput Isn't a Guess—It's a Calculation You Can't Afford to Skip
Peak throughput gets treated like a gut feeling far too often. Teams pick a number that feels safe for their workload, deploy, and then act surprised when peak hours crush the system. The truth is that peak throughput is a deterministic value: it's the product of concurrency, latency per operation, and resource headroom. If you don't compute it before launch, you're not planning capacity—you're waiting for an incident to do the math for you.
For a service handling 10,000 requests per second at 50 ms median latency, you need roughly 500 in-flight operations just to stay level. Add serialization, connection pool limits, and garbage collection pauses, and that number shifts quickly. Writing down the formula and plugging in real measurements from load tests turns an abstract risk into a number you can argue about, adjust for, and monitor against.
Skipping this calculation doesn't save time. It transfers the cost to your on-call rotation. Even a rough estimate with stated assumptions beats a blind rollout, because it forces you to name the limits before users do.
Safety Mechanisms That Go Beyond the Obvious Emergency Stop
Most industrial machines ship with an emergency stop button, but the real safety story happens long before anyone slaps that red mushroom. Modern equipment quietly monitors its own pulse through redundant sensor arrays, cross-checking torque, temperature, and vibration data against safe operating envelopes dozens of times per second. When values drift even slightly outside expected patterns, the system doesn't wait for a human to notice—it initiates a controlled slowdown, reroutes power, or isolates the affected axis while keeping the rest of the process alive. This preemptive approach catches faults during the awkward middle stages, where traditional e-stops would either trigger too late or not at all.
Another layer hides in the software architecture itself. Instead of relying on a single watchdog timer, advanced controllers run parallel safety logic on physically separate processing cores, comparing outputs every few milliseconds. If one core disagrees due to electromagnetic interference, a code glitch, or aging silicon, the machine enters a passive state without any mechanical contactors needing to open. This kind of diverse redundancy means the machine can distinguish between a transient sensor hiccup and a genuine hazard, reducing nuisance stops that cause operators to bypass guards out of frustration.
Finally, there's the human factor woven into the hardware. Some machines embed capacitive sensing into their frames, detecting the difference between a gloved hand resting on a cover and a stray tool brushing past. Others project temporary light curtains that appear only during automatic cycles, disappearing when the operator steps in for manual loading. These mechanisms don't replace the emergency stop—they make it the last resort in a chain of interventions that feel less like interruptions and more like natural pauses in the workflow.
The True Cost of Downtime Hides in Maintenance Intervals and Parts Access
When a machine stops, the visible losses—missed production targets, idle workers, rushed overnight shifts—are easy to tally. But what quietly drains the budget month after month are the choices made around maintenance intervals and how quickly spare parts can be reached. A pump that gets serviced every 2,000 hours because that’s “how it’s always been done” might actually need attention at 1,400 hours on this particular line, where vibration and heat cycles differ from the manual’s assumptions. Each premature failure triggered by that mismatch doesn’t just cost a seal or bearing; it cascades into unplanned downtime, emergency freight for parts from a distant warehouse, and overtime for a crew already stretched thin.
Parts access is often treated as a procurement issue, but it’s really a maintenance strategy problem. A plant that keeps critical spares in a locked cabinet three buildings away, or relies on a supplier with a two-week lead time for a common motor, has baked in a hidden tax on every repair. The true cost shows up in the hours spent waiting at the dock, the temporary workarounds that fail again a week later, and the slow erosion of trust in the maintenance schedule itself. Compare that to a site where a few extra fast-wear items are stocked near the line and the CMMS actually flags when the last one is used—the same failure might cause a 45-minute swap instead of a three-day standstill.
The real trap is that these costs rarely appear on a single invoice. They’re spread across dozens of line items: extra shipping, expedited machining, higher energy use from degraded equipment, and the quiet loss of production capacity that never gets reported because it happened on a weekend. To see the full picture, you have to stop asking “What did this breakdown cost?” and start asking “What would it have cost to prevent it?” Often the answer is a fraction of the downtime number—but only if you’re willing to revisit maintenance intervals based on actual data and rethink where your spare parts live before the next stoppage.
Hydraulic or Electric Drive Each Breaks Down Differently Under Load
When a hydraulic drive works against a stubborn load, it rarely quits without warning. Internal leakage across seals and valve clearances increases as pressure climbs, so the system gradually loses force. Oil heats up, viscosity drops, and movements turn spongy. Operators often feel the machine struggling to hold position or notice cycle times stretching before a total failure occurs. That slow decay leaves room to schedule maintenance.
Electric drives behave differently under the same stress. Overload protection usually kicks in fast, folding back torque or tripping a fault before mechanical damage spreads. The shutdown can feel abrupt, even if the underlying problem has been building for hours. Windings may overheat, insulation ages, and connectors loosen, but the visible symptom is often a clean stop rather than a gradual loss of strength. This means electric systems can hide cumulative wear behind protective trips, catching operators off guard when the drive finally refuses to restart.
Floor Space, Noise Ceilings, and Power Hookups Shape the Final Choice
A rack can look perfect in a spec sheet and still fail the moment you try to roll a loaded server into place. Floor space is the first filter. Measure the actual room, not the marketing numbers. Door swing, aisle clearance, and even the path from the loading dock matter more than total square footage. A cabinet that fits the floor plan but blocks airflow or makes cable runs impossible will haunt you for years. Walk the space with a tape measure and a floor plan, and mark every obstruction before choosing a footprint.
Noise ceilings rarely make the spec sheet, but they make or break the room. Fans, power supplies, and cooling units add up fast. If the rack sits in an open office or near a conference room, high-RPM fans will become a daily complaint. Look for acoustic ratings, fan curves, and sound-dampening options. A quieter cabinet might cost more upfront, but it saves the team from headphones and hallway arguments.
Power hookups decide what you can actually run. Count the outlets, check the amperage, and verify the plug types before buying. A rack with plenty of vertical space but only two 15-amp circuits is a trap. Map your devices to the power strips, leave headroom for startup surges, and confirm the building can deliver what the cabinet demands. Without clean, reachable power, even the best floor plan and the quietest fans are irrelevant.
FAQ
Different models handle paper, plastics, metals, or mixed waste. Identify the hardest material you'll feed it and choose a cutting chamber and blade configuration designed for that load.
Throughput requirements determine motor size and feed opening. If continuous feeding is needed, look for a model with an extended duty cycle and a larger hopper rather than a batch-fed unit.
Yes. Three-phase industrial power supports larger motors, while single-phase units limit you to lighter work. Check your available voltage and phase before shortlisting models.
Emergency stop bars, auto-reverse on overload, safety interlocks on hoppers, and thermal protection for the motor. These protect operators and prevent costly jams.
Very important if the output will be recycled or needs to meet disposal regulations. Look for models with adjustable screens or multiple cutting stages to achieve a uniform chip size.
Heavy-duty shredders need blade sharpening or replacement, gearbox oil changes, and periodic belt tensioning. Choose a model with easy access to the cutting chamber and a local source for wear parts.
Some units are built for dry paper only, while others can take wet wipes, metals, or tough plastics. Check the manufacturer’s torque rating and blade hardness for abrasive feeds.
Larger shredders take up more floor space and generate more sound. If the unit will run near workers, look for a sound-dampening enclosure or plan for a separate room.
Conclusion
A heavy-duty shredder only earns its keep if its cutting chamber, rotor type, and tooth geometry match what actually goes into the hopper. Dense metal turnings demand different torque characteristics than bales of plastic film, and guessing wrong means plugging, bent shafts, or a drive system that stalls mid-shift. Throughput is not a marketing number—it is the product of feed rate, material density, and continuous duty cycle. Instead of fixating on peak horsepower, calculate the pounds per hour you really need, then add headroom for batch spikes and wear. Safety goes beyond the red button, too: look for auto-reversing jam logic, feed ram interlocks, and lockout provisions that let maintenance crews clear a rotor without a long isolation sequence.
Downtime quietly eats profit when wear parts hide behind a dozen bolts or a hydraulic pack runs hot after three hours of continuous load. Check the maintenance intervals and whether common items like screens and counter-knives are reachable without a crane—then compare that access against the real cost of a lost production shift. Hydraulic drives tend to forgive shock loads and recover from jams smoothly, but they generate heat and need clean oil more often. Electric drives can offer better energy efficiency and finer torque control, yet a sudden stall may trip breakers or stress gearboxes. Finally, the best spec sheet means nothing if the machine does not fit your floor plan, exceed your noise ceiling, or connect to available power. Match the model to the building before you buy, not after the rigging crew arrives.
Contact Us
Contact Person: Leon
Email: [email protected]
Tel/WhatsApp: 8615385558866
Website: https://www.shred-waste.com